
For two years, parsing unstructured text has stayed inefficient. As a senior technical editor here at The AI Aura, I review dozens of enterprise architectures weekly. A glaring bottleneck always appears in the exact same spot.
Developers force massive System Two Large Language Models to handle mundane chores. These models pull dates and invoice numbers out of customer emails. In short, teams ask high-reasoning engines to act like simple parsers. This setup works most of the time. However, it remains expensive, sluggish, and prone to formatting errors.
The conversation shifted when TypeSafe introduced Jev last month. The project drew inspiration from Daniel Kahneman’s concept of fast System One thinking. Jev proved that single-pass decision models excel where heavy LLMs struggle. Yet Jev handled only classification. For most engineers, the primary headache remains raw data extraction.
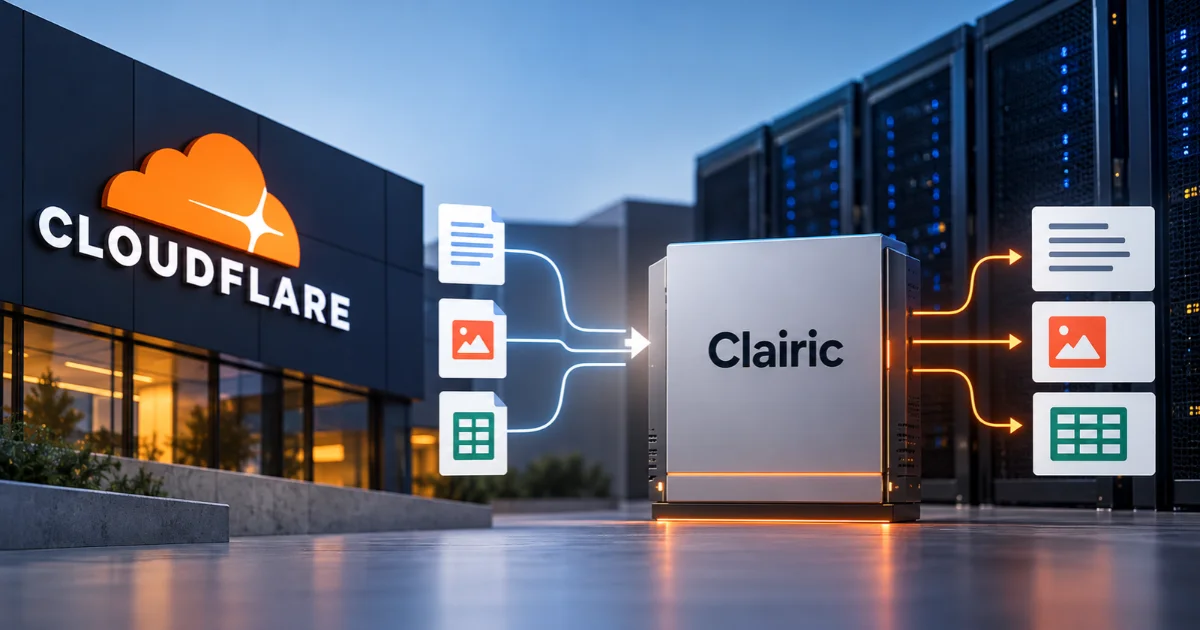
Cloudflare recognized this gap and just dropped a preview of Clairic. Hosted on Workers AI, it is the first true System One extraction model, designed to pull, compute, and forecast values from messy data at a fraction of the cost and latency of a standard LLM, highlighting a broader shift in the debate over Specialized vs. Generalist AI: Which Model Wins the Generative War?
Moving Beyond Expensive Generation Pipelines
Standard extraction pipelines are notoriously fragile. Most engineering teams have to staple together complex schema validators, rigid prompt engineering, and endless retry loops just to ensure a generative model spits out valid JSON. You pay a heavy toll in output tokens for every single field, and if a digit gets misread during the generation phase, the entire application breaks.
Clairic completely abandons this token-generation paradigm. It does not write answers. Instead, it processes the input context in a single parallel forward pass without generating new text.
This means the model directly identifies character offsets within the source text, returning exact spans so you can instantly verify where a piece of data actually originated.
According to the architecture breakdown published over on the Cloudflare blog, this zero-generation approach also allows the server to split massive field requests into parallel streams that evaluate the whole input simultaneously before merging the results.
Whether you ask for three data points or thirty, the latency and cost remain essentially identical. It handles multimodal inputs just as seamlessly, parsing through poorly lit, angled receipt photos without requiring pre-sanitized text layers.
Precision Over Plausible Guesses
What makes this release genuinely compelling for production environments is its inherent skepticism. Frontier LLMs are eager to please, often inventing details to satisfy an output schema a core challenge explored in AI Hallucinations Explained: Why ChatGPT Sometimes Gets Facts Wrong.
Clairic behaves differently. Every scalar answer it produces comes bundled with a null probability metric and a strict confidence score. If a piece of requested information simply does not exist in the source document, the model returns a cleanly typed null rather than stringing together a plausible lie.
The model can also execute bounded computations on the fly without explicit prompting. If a customer email mentions an order arrival date and today’s date, Clairic natively returns the precise duration of days between the two. It can read a subtotal and a tax line, combine them, and return the final amount strictly formatted to two decimal places.
Everything is constrained to the exact parameters you set, whether that is a rigid date format or a forecasted statistical distribution. We are finally moving toward a mature, modular ecosystem where System One models like Clairic rapidly parse reality, specialized models route the logic, and massive LLMs are reserved purely for the high-level reasoning they were actually built for.