
When a major artificial intelligence platform experiences a service disruption, the ripple effects are felt instantly across the tech community. On a busy weekday, developers, enterprise teams, and casual users suddenly found themselves locked out of their workflows as Anthropic faced widespread operational hurdles.
The company acknowledged a significant degradation in performance that severely impacted user access and system reliability. For professionals who have deeply integrated machine learning models into their daily production environments, this sudden loss of connectivity was a stark reminder of our growing dependence on cloud-based AI infrastructure.
Frustration mounted as routine tasks like drafting documents, generating code snippets, and querying large datasets ground to a halt. Instead of seamless interactions, users encountered persistent authentication failures and dropped sessions.
This disruption sparked a flurry of activity on community forums and social media as people tried to determine whether their accounts had been compromised or whether a server-side issue caused the problem.
The Scope of the Service Disruption
The problem extended far beyond a simple web interface glitch. As the incident unfolded on November 13, 2026, technical difficulties began spreading across Anthropic’s entire product ecosystem.
Users trying to access the main chatbot dashboard found themselves abruptly logged out, while developers relying on backend integrations watched their applications lose communication with Anthropic’s network.
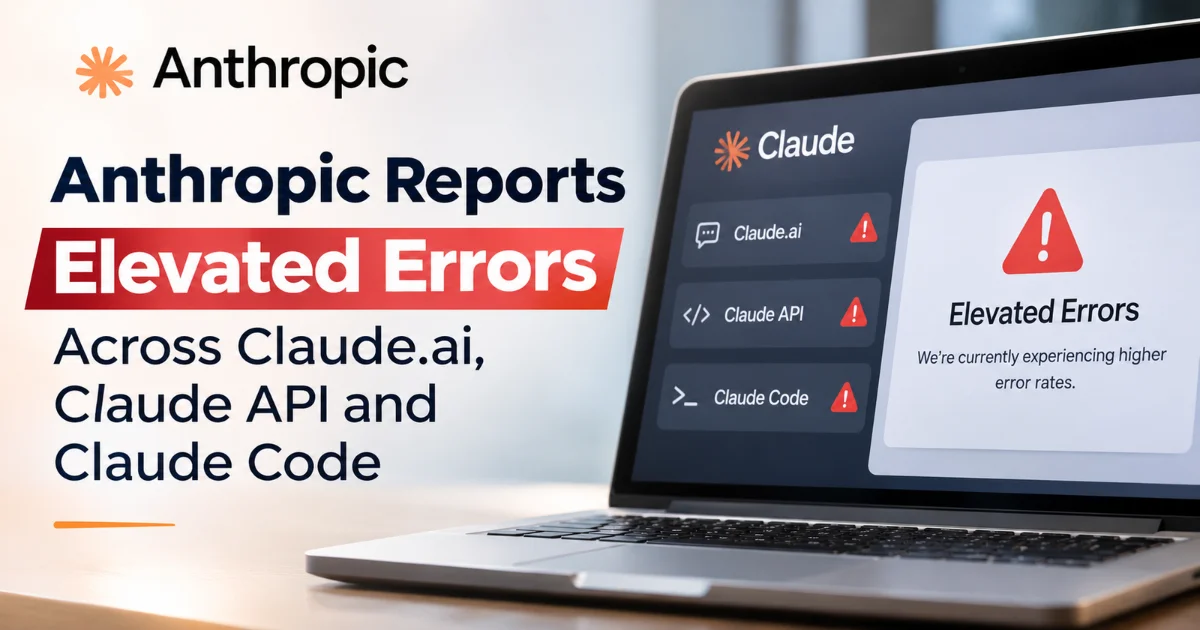
According to Anthropic, the engineering team actively investigated reports of degraded performance affecting a massive variety of surfaces, which heavily impacted the Claude API and Claude Code.
The disruption also crippled essential workspace connectors, temporarily breaking functionality for Claude Docs, Claude Sheets, and enterprise-level tools like Claude Security and Managed Agents.
Mobile applications suffered the exact same fate, leaving users completely disconnected on the go. This level of systemic failure illustrates how deeply intertwined these services actually are.
When the central authentication or routing protocols encounter heavy friction, the resulting bottleneck suffocates everything down the line. It essentially freezes the workflow of software engineers who rely on the AI for real-time debugging, as well as business analysts who depend on automated document processing.
How Interconnected Ecosystems Handle Downtime
Managing a massive generative AI platform requires orchestrating a staggeringly complex web of compute resources, data routing, and real-time security checks.
When a major incident like this occurs, the recovery process is rarely a simple switch flip. As the engineering teams pushed updates and stabilized the authentication protocols, recovery happened in stages rather than all at once.
The first signs of life usually return to the main web interface, but backend connectors and scheduled API routines often take significantly longer to clear their backlogs.
In this specific event, while direct chatting capabilities gradually returned to normal levels, tasks involving external workspace connectors and automated security scans remained sluggish for hours. The situation highlights a critical vulnerability in modern development environments.
Because companies increasingly rely on interconnected microservices, a single point of failure in an AI provider’s authentication layer can temporarily paralyze an entire corporate tech stack. It forces engineering teams to reckon with the reality of cloud computing limits and emphasizes the absolute necessity of building resilient, local fallback systems.
As these platforms continue to evolve and capture more market share, the industry will inevitably demand stricter service level agreements and more robust architectural redundancies to prevent a singular software hiccup from halting global productivity.